

Iris Dataset · Ace Data Cloud

Iris Flower Dataset:
A Classic Starting Point for Machine Learning

A classic classification dataset released by statistician R.A. Fisher in 1936. 150 samples, 3 species, 4 features—simple, clean, and perfect, it is the ideal first step for learning machine learning and data analysis.

Iris Flower Dataset
CSV included · 4.4 KB CC BY 4.0 License In use since 1936
📊
150
Number of Samples
🌸
3
Flower Species
📐
4
Feature Dimensions
📅
88+
Years of Use

Dataset Highlights

There are good reasons why the Iris dataset has become the "Hello World" of machine learning

⚖️

Balanced Classes

Each of the three species (Setosa, Versicolor, Virginica) has 50 samples, perfectly balanced, with no need for oversampling or undersampling.

✨

Simple and Clean

No missing values, no outliers, and no complex data cleaning required. The 4.4 KB CSV file contains all the data and is ready to use out of the box.

🎓

Ideal for Beginners

A standard teaching dataset in machine learning courses worldwide. From KNN to neural networks, it can be used to demonstrate almost any classification algorithm.

📈

Visualization-Friendly

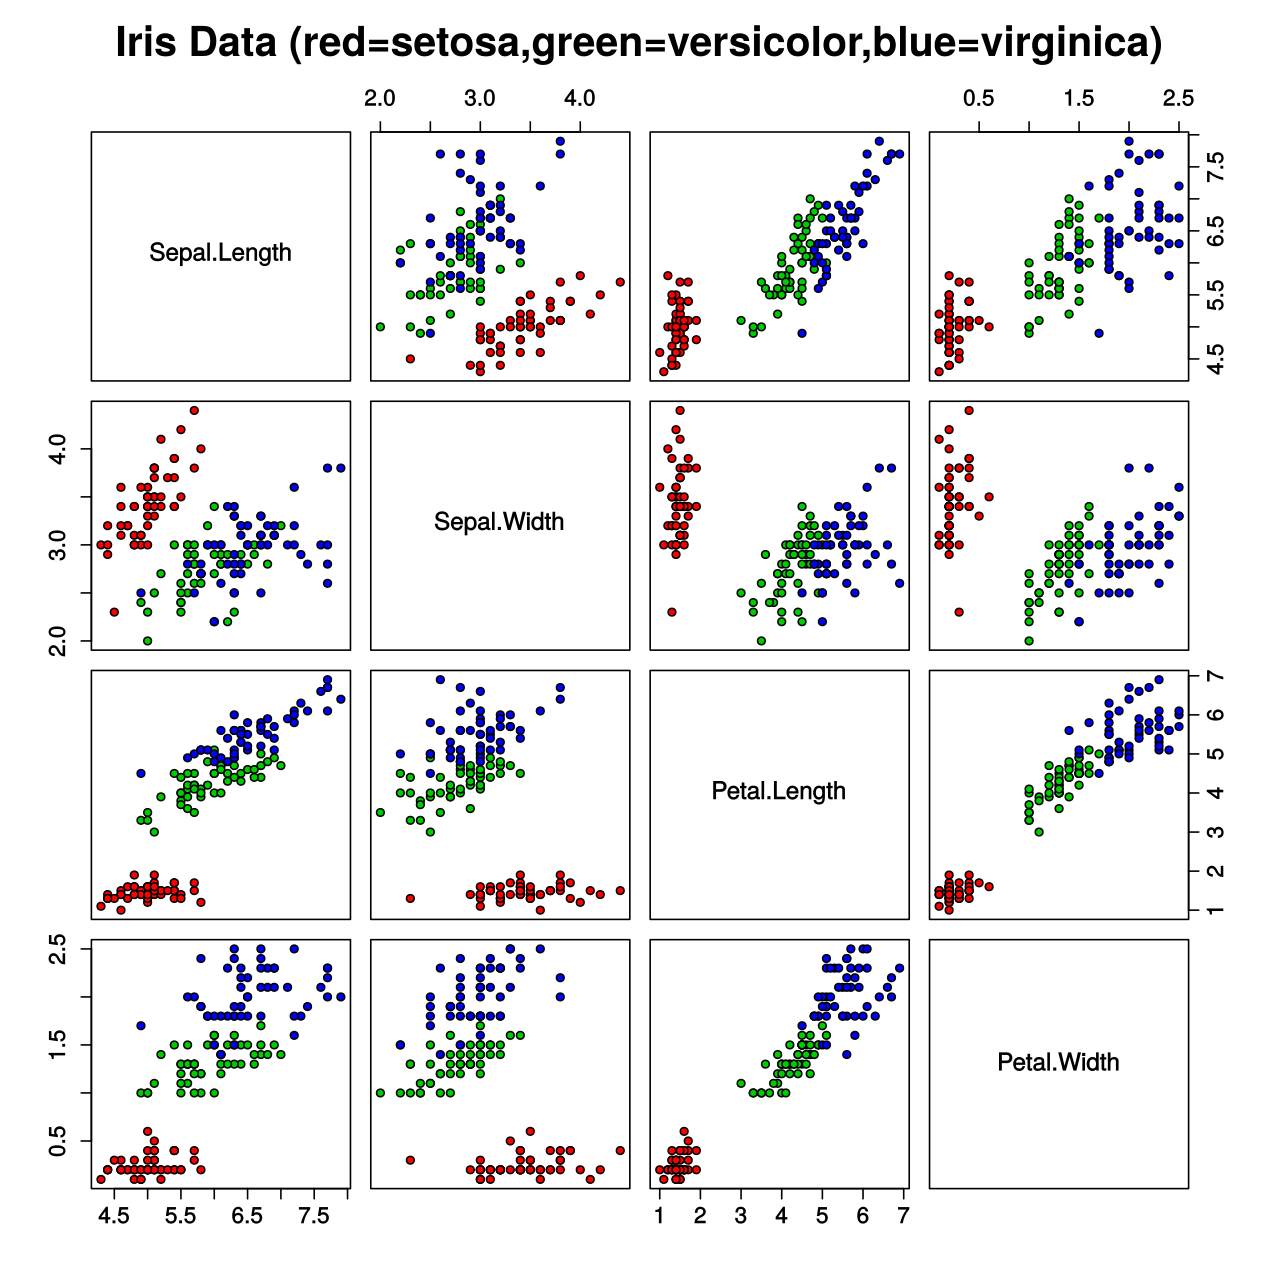
The 4 numerical features are ideal for creating scatter plots, box plots, heatmaps, and pair plots, intuitively showing distribution differences between classes.

📚

Extensively Documented

As one of the most cited datasets in statistics and machine learning, it has a vast number of tutorials, papers, and reference implementations.

📜

CC BY 4.0 License

Released under a permissive Creative Commons license, it may be freely used for learning, teaching, research, and commercial projects, with attribution required.

Use Cases

From classroom exercises to algorithm benchmarking—the common uses of the Iris dataset

🤖

Classification Algorithms

KNN, SVM, decision trees, random forests, logistic regression—the preferred dataset for validating any classifier

📊

Data Visualization

Create scatter plots, pair plots, and parallel coordinate plots to intuitively understand the class structure of multidimensional data

📐

Statistics Education

Used to explain core statistical concepts such as discriminant analysis, principal component analysis (PCA), and hypothesis testing

🏆

Algorithm Benchmarking

Quickly compare the accuracy, recall, and F1 score of different models on standard data

Data Preview

Sample records from the Iris dataset (CSV format)

CSV
sepal_length,sepal_width,petal_length,petal_width,species
5.1,3.5,1.4,0.2,setosa
4.9,3.0,1.4,0.2,setosa
7.0,3.2,4.7,1.4,versicolor
6.4,3.2,4.5,1.5,versicolor
6.3,3.3,6.0,2.5,virginica
5.8,2.7,5.1,1.9,virginica
sepal_length Sepal Length sepal_width Sepal Width petal_length Petal Length petal_width Petal Width species Species

Get Started in 3 Steps

From browsing to using, in just a few minutes

01

Browse the Dataset

View the Iris dataset's detailed description, field definitions, and data preview on the Ace Data Cloud platform.

02

Purchase and Download the Delivery Package

After logging in, request the dataset and purchase the US$0.99 plan. Download the ZIP delivery package containing the original 4.4 KB CSV, source attribution, and CC BY 4.0 license.

03

Load and Use

Load the data with Python, R, or any data analysis tool, and start training models or creating visualizations.

Python
import pandas as pd
from sklearn.model_selection import train_test_split
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score
# Load data
df = pd.read_csv("iris.csv")
# Split the training and test sets
X = df[["sepal_length", "sepal_width", "petal_length", "petal_width"]]
y = df["species"]
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.3, random_state=42
)
# Train a random forest classifier
clf = RandomForestClassifier(n_estimators=100, random_state=42)
clf.fit(X_train, y_train)
# Evaluate accuracy
y_pred = clf.predict(X_test)
print(f"Accuracy: {accuracy_score(y_test, y_pred):.2%}")  # Output: Accuracy: 100.00%

Start Your Machine Learning Journey

First view real samples and fields; after purchasing the US$0.99 plan, download the complete data package with source and license information.